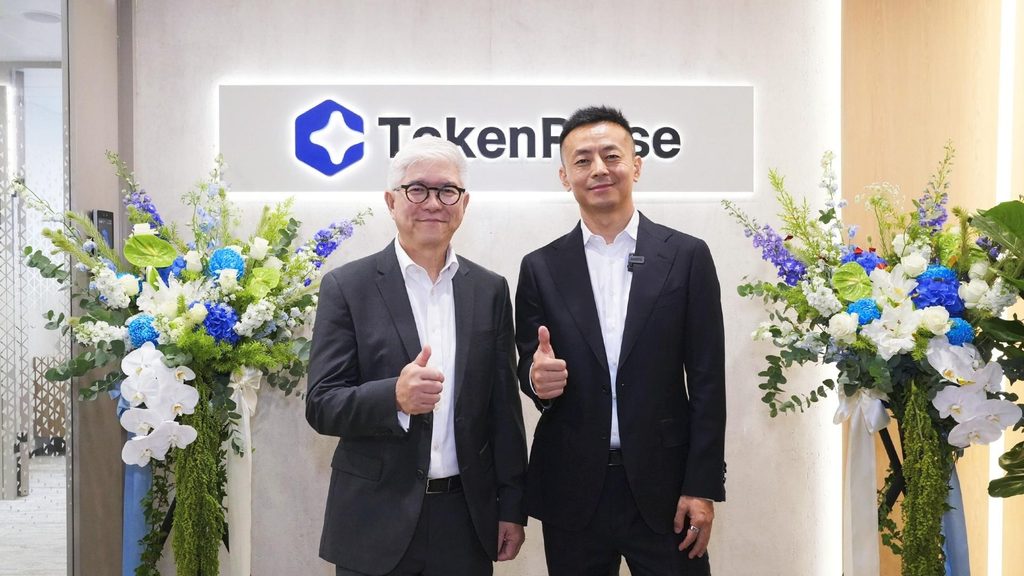
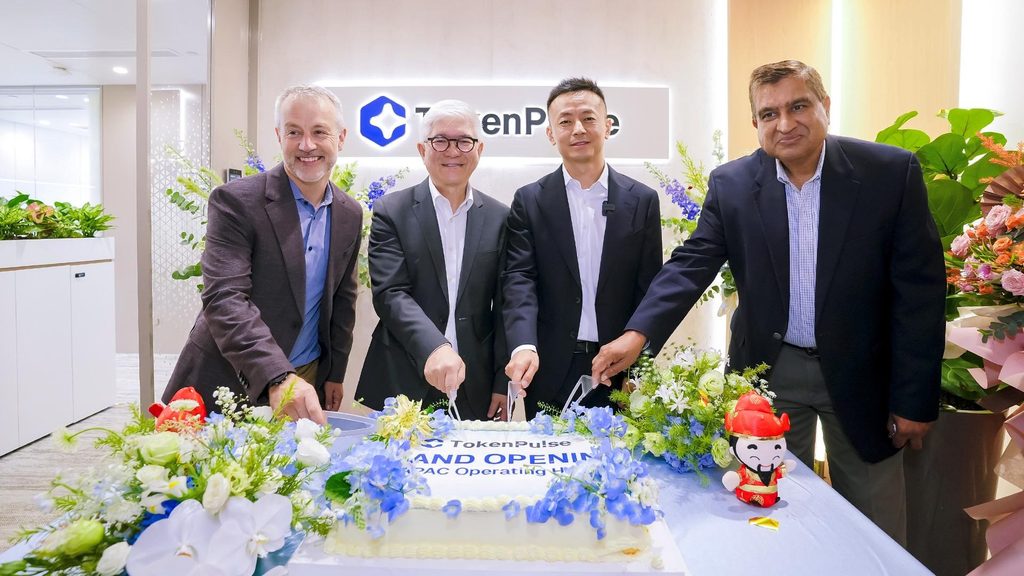
SINGAPORE AND SAN FRANCISCO — TokenPulse has opened an Asia-Pacific Operating Hub in Singapore, expanding the company’s presence in a region where demand for AI applications and computing capacity continues to grow.
The AI inference infrastructure company, headquartered in San Francisco and Singapore, marked the opening with a ceremony attended by industry leaders and ecosystem partners. The gathering focused on developments in AI compute and opportunities to build global infrastructure.
Businesses bringing AI products into production must manage the cost of inference while delivering quick, reliable responses. They also need infrastructure that can grow with demand. Gartner projects the global AI infrastructure market will increase from $982 billion in 2025 to $1.98 trillion by 2027.
TokenPulse serves foundation model companies, AI platforms, enterprises and AI-native applications. Its offering brings together data-center resources, GPU infrastructure, an inference engine and coordinated serving capabilities across regions.
A Team with Global Infrastructure Backgrounds
The company’s leadership and technical teams have experience spanning AI and machine-learning infrastructure, cloud computing, networking, data centers and international operations. Their professional backgrounds include Microsoft, Google and Equinix.
Steven Zhou, TokenPulse’s CEO, has more than 20 years of experience growing businesses in the United States and Asia. Chairman Thomas Pang has worked for more than 30 years across government, investment, infrastructure and corporate leadership. He spent over two decades at Keppel and led Keppel’s Data Centres & Networks Division as CEO from 2014 to 2024, overseeing its data-center and digital-connectivity businesses worldwide.
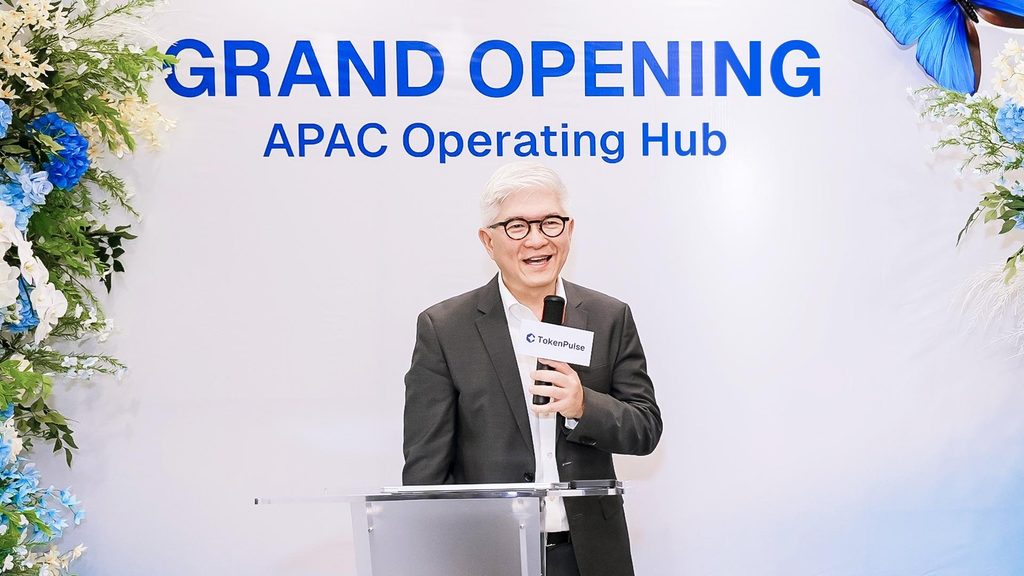
“Singapore is a natural choice for building our APAC operating hub, given its mature data center ecosystem, strong network connectivity and deep talent pool,” said Pang. “Our foundations are rooted in decades of experience across data centers, networking and cloud computing. Drawing on that experience in building and operating infrastructure at scale, we will continue investing in compute capacity and ecosystem support, delivering the best performance at the lowest cost per token.”
Singapore’s Role in TokenPulse’s Regional Strategy
TokenPulse is building infrastructure across North America, Asia-Pacific and Europe. Singapore will serve as the company’s strategic base for APAC, connecting North American AI technology, customers and capital with Southeast Asia’s expanding data-center and energy resources.
The Singapore hub will help TokenPulse coordinate regional operations and infrastructure partnerships. The company plans to work with partners in Malaysia, Indonesia, Thailand and other markets across the region, supporting its goal of locating compute capacity closer to customers and their workloads.
TokenPulse is pursuing several data-center projects with infrastructure partners in key markets. Its longer-term plan is to bring together data-center, energy and compute resources to support growing inference demand. The roadmap includes deploying the latest-generation NVIDIA AI infrastructure. Engineering efforts will also focus on improving the amount of useful AI output generated from available compute.
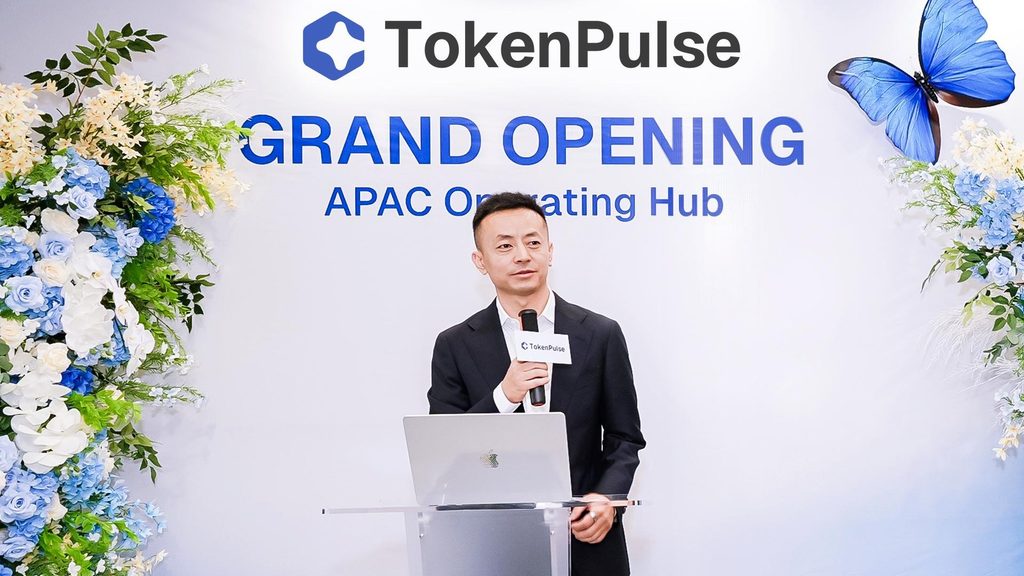
“AI is undergoing a fundamental shift: compute demand is moving from training to inference,” said Zhou. “For businesses, inference is no longer a hidden cost sitting in the background. It is becoming a core competitive factor in determining whether AI products can successfully reach the market.”
He added: “As one of the fastest-growing regions for AI applications, developers in Asia Pacific are direct about cost and performance. By making Singapore our co-headquarters and APAC operating hub, we are putting our compute and our team closest to them to deliver better performance at lower cost.”
Consumption and Deployment Choices
TokenPulse provides three ways for customers to access compute through a unified technology stack. The models are intended to accommodate different workload sizes and allow customers to expand as usage grows.
- Serverless — Pay per token: API access for deployment, model evaluation and variable workloads, without an initial commitment to dedicated GPU capacity.
- On-demand — Pay per GPU-hour: Dedicated endpoints and predictable performance for customers with changing compute requirements.
- Reserved — Contracted capacity: Dedicated compute for sustained workloads or customized infrastructure needs.
Customers can choose from three deployment models based on their technical and operational requirements:
- TokenPulse Cloud: Managed GPU infrastructure for customers seeking a streamlined route to production.
- Private VPC: A TokenPulse-hosted environment with a dedicated network boundary and workload isolation.
- BYOC (Bring Your Own Cloud): Deployment of the TokenPulse inference engine within a customer’s cloud or VPC, or on the customer’s own GPUs.
The company describes its approach as “Start small. Scale without replatforming.” Customers can begin with API-based access to validate an application, then move to GPU services or reserved capacity as requirements change. TokenPulse says this progression allows customers to expand without changing providers or rebuilding their platforms.
Inference Optimization for Production Workloads
TokenPulse combines data-center infrastructure with inference optimization tailored to industry use cases. The company says it optimizes open-weight models for vertical workloads to improve compute efficiency and serving throughput, helping customers process more tokens at a lower cost.
Reported capabilities include:
- Improved cache use: HiCache and a multi-tier key-value (KV) caching architecture are designed to reduce repeated computation. TokenPulse reports that its observed cluster-level cache hit rate can reach 95%.
- Reduced response times: In tests with context parallelism enabled, the company reports a 50% reduction in 90th-percentile time to first token (P90 TTFT) and a 75% reduction in 99th-percentile time to first token (P99 TTFT), compared with the same workload without context parallelism.
- Intelligent global routing: TokenPulse’s routing architecture directs requests across serving regions using factors such as customer requirements, model, region and time window. Near-edge access, session-context reuse and redundant network paths are intended to support responsive service, availability and efficient compute utilization.
The company says these capabilities are designed to help AI businesses manage inference costs while meeting the performance and reliability needs of production systems. Results depend on workload and operating conditions.
About TokenPulse
TokenPulse is an AI inference infrastructure company headquartered in San Francisco and Singapore. Its platform combines the latest-generation GPU infrastructure, an optimized inference engine and global infrastructure capabilities for foundation model companies, AI platforms, enterprises and AI-native applications.
Customers can choose Serverless, On-Demand or Reserved compute, starting with API-based inference and expanding to dedicated GPU capacity as their workloads grow.
Learn more: www.tokenpulse.com